How the desk learns
The Learning tab answers three questions in order (is the desk getting better, what does it keep getting wrong, what is it doing about it), then lists the rest of the grades and folds the machinery under "How this works".
- Who it is for
- Owners & operators
- Reading time
- 11 min read
- Updated
The desk is meant to get better at its own jobs from its own history, a little every day, without anyone editing prompts by hand. Desk › Learning is where you watch that happen. The page answers three questions, in this order, in plain words. Everything on it is counted by code after the close, never by the model grading itself, and none of it changes trading on its own.
- Owns
- Nothing an agent reads: the grades, repeated-mistake counts and the list are for you
- Reads
- Sessions, , fills, daily prices, the 's findings, the automatic session review, the lessons the agents wrote
- Runs
- After the close, in the same slot as the : settle outcomes, grade each role, refresh , queue memory clean-ups
- Change it at
- One lever: hide a lesson from the desk under Lessons applied (lesson visibility· Desk › Learning › Lessons timeline › Hide from the desk)
Is the desk getting better?
Each of the three panels is set the same way: the question in small quiet type, then the answer as the panel's largest line, then one or two sentences that explain it. The first answer is one of Yes, Not yet, Partly, It is holding steady or It is too early to say. The page does not judge this by eye. It counts two things the grading code has already decided:
- a role's tracked grade whose last two months differ by more than chance alone would explain (an exact statistical test, run on each role's one tracked grade only; the pill beside it reads , in a neutral color whichever way the figure moved), and
- a repeated mistake that now happens clearly more or clearly less often than this desk's own usual rate.
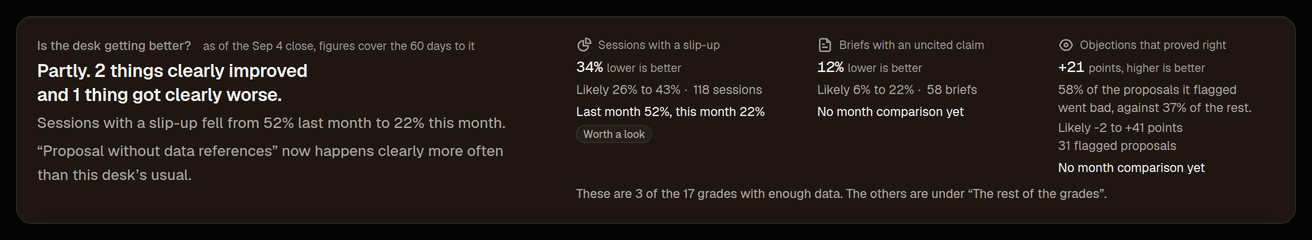
Nothing clearly better or worse, with two months of a tracked grade the test could compare, is "holding steady". Nothing to compare yet is "too early to say". The sentence under the answer names what moved. Worth a look is deliberately neutral: it may be noise or a real shift, and the right response is to read the sessions, not to change a setting.
Beside the answer sit at most three numbers, and only grades that have enough data: a grade with two measured months to compare comes first, then each role's tracked grade (Portfolio Manager, then , Critic, ), then other measured grades. Under each number are short facts, not sentences: which way is good, the range the true figure most likely lies in and what it was measured over (Likely 15% to 23% · 364 sessions), then last month beside this month. Every figure in the panel covers the same trailing window, which the panel says once beside the date (as of the Sep 4 close, figures cover the 60 days to it). Only a tracked grade says No clear change (the test looked and found none); every other grade shows its two months and leaves the judgment to you. A number whose two months are not both measured says No month comparison yet. A grade without enough data never appears here.
The Critic's number is a difference (+21 points), so the tile says of what: 58% of the proposals it flagged went bad, against 37% of the rest. The count beside it is the proposals it flagged, which is what its floor counts.
What does it keep getting wrong?
The panel opens with its answer (5 mistakes keep coming back. 1 is getting worse and 1 is improving.). When the automatic session review or the Critic catches the same mistake more than once (a proposal without data references, a moved goalpost, a brief claim without a source), it is one row in the table under it: whose mistake it is, the mistake and the instruction it falls under, how many times in the last 14 days, a status, and links that open the latest example and the one before.
The status is a word the grading code computed against this desk's own usual rate:
- Worsening only when it now happens clearly more often than usual, not just once or twice more.
- Improving only when it happens clearly less often than usual.
- Watching while it is too close to the usual rate to call, or while there is not enough history to have a usual rate.
A short phrase beside the status says why ("usual is about twice", "new in the last 14 days", "too early: 21 of 74 days"), with the full sentence when you hover it. On a young desk every row is too early for the same reason, so the page says it once above the table instead of on every row: The desk needs 74 days of history to know what is usual for it, and has 21. "Usual" is how often the mistake happened on this desk over the 60 days before the 14 being counted. The four status words are explained, one row each, under What the status words mean. A mistake not seen for 14 days leaves the table. These counts come from code, never from the lessons, so retiring a lesson cannot make a mistake look fixed.
What is it doing about it?
The panel opens with its answer, built from the three lists under it (It has changed its own lessons 10 times and queued 4 clean-ups for its next end-of-day session. Nothing is waiting on you.). When something is waiting on you, that leads. Then three groups, each with its count beside its name and its list under it.
Lessons applied. Lessons are notes an agent writes to itself after the close (memory). The list shows every change, newest first (when you have hidden a lesson or shown one again, that entry is in the list too and is counted as yours, not the desk's), with the before and after: learned, noticed again, pinned, merged (two lessons folded into one, in the agent's own restated words), reworded, kept after review, retired.
You do not write, edit, merge or restore lessons: they are the agent's own experience, and an operator-authored "lesson" would be a in disguise (write guidance instead). Your one lever is : the lesson stops appearing in the , the row is untouched, and the agent sees hidden by operator with your reason in its next end-of-day session, where it must either retire the lesson or say why it should stay; it may not quietly write the same rule again. Hiding needs a reason and no code, because it can only reduce a lesson's influence. If the agent later a hidden lesson into another one, your hide follows the merged lesson until you lift it. Show to the desk again lifts it. Both are in the audit log.
Clean-ups queued. What the nightly tidy-up has queued: two lessons that say the same thing (with the longer wording on file as a starting point), a lesson that quotes a limit the book no longer has, one nobody has seen in six weeks, one you hid. The Portfolio Manager answers each in its end-of-day reflection (fold two into one in its own words, reword, retire, or keep with a reason), and the answer shows up under Lessons applied the next morning. A merge or rewording that adds anything the original lessons did not say is refused and the item stays queued; so is any "lesson" that claims an edge ("wins 70% of the time") or talks about a score. Each row says what is asked, when it was queued and when the request lapses (Merge 2 lessons · queued 19 hours ago, expires in 14 days). Each item expires after two weeks if unanswered, and an unanswered item a slip-up in the session review. These are the agent's to answer, so there are no buttons here and they never appear in the Inbox.
Waiting on you. Suggested fixes to the desk's instructions, drafted from repeated mistakes, will wait here (and in the Inbox) for your yes or no. That step arrives in a later release; until then this group says Nothing is waiting on you, and tells you how many lessons you have hidden.
The rest of the grades
Every measured grade that is not one of the three numbers at the top is a row here: the figure, the likely range (a 95% interval that accounts for decisions made on the same day moving together), what it was measured over, and this month against last where a row has two measured months to show (only each role's tracked grade is compared month to month by the test, so when no row has a pair the column is left out and the page says so once). A grade marked Context (ideas that worked, brief calls that came true) describes results, not skill, and never triggers anything.
Everything without enough data is one line that counts both cases: 13 grades need more history. 5 are on course, the first around Sep 11. 8 will not get there at the desk's pace so far. A grade over seven decisions is noise dressed up as a number, so every grade is held to a floor (about 20 sessions for rates, 30 settled decisions for confidence accuracy, 20 flagged proposals for the Critic). Below it the page shows only how far along the grade is, for example 3 of 30 decisions: no value, no color, no arrow. Open the line to see which grades are waiting, how far each one is, and the day each is ready if the desk keeps its pace. A grade counts inside a trailing 60-day window, so a day is named only while the desk is younger than that window and on course to fill it; a grade that would not get there at the desk's pace says not at this pace instead of a date. At a normal pace the Portfolio Manager's grades fill first, within a few weeks. A grade the desk cannot measure at all yet says so in a sentence.
What each role is graded on:
- Portfolio Manager: confidence accuracy (how close its stated confidence was to what happened, beside the score of just guessing the base rate), whether it kept to its own stops, whether buy ideas named a stop, slip-ups per session from the automatic review, sessions with a slip-up (its tracked grade), repeated known mistakes, cost per decision, sessions that acted.
- Researcher: briefs with an uncited claim (its tracked grade), sources per brief, slip-ups per brief, and brief calls that came true (context).
- Critic: objections that proved right: how much more often a trade went bad when the Critic objected than when it did not (its tracked grade), time to answer a finding, and how often the PM overruled it and the trade then went bad.
- Consult: questions left unanswered (its tracked grade) and suggestions you accepted.
The agents never see any of this. A model that can read its own scoreboard learns to please the scoreboard; the PM's state card carries at most one line about the Critic's track record, and only once there are twenty flagged proposals behind it.
How this works
The machinery sits behind the fold at the foot of the page, closed until you open it. The fold's own row says how far the loop goes for this book: measuring only, nothing here changes how the desk trades, or recording only, nothing is graded when grading is switched off and sessions are still recorded. Inside:
- Record. Every session is written down with the exact instructions, memory, model and rubric it ran under, so a grade can say which version it describes. The step reads Ran, with how long ago the last session was recorded, whenever your desk is recording, and it reads Missed only when sessions were recorded before and none has been for two trading days. It looks at the recordings themselves, so a desk that is recording never shows as off. A brand new book reads Not run yet until its first session.
- Settle. After the close, code works out what happened to each decision (proposals, including the ones the rejected or that expired; position ; the Researcher's checkable calls) from daily prices and the book's own fills. A decision stays "open" until its horizon has passed, then it is settled once and never re-scored.
- Grade. Each role gets a small set of grades with honest sample sizes (above).
- Tidy memory. A nightly pass looks for duplicate, stale or contradictory lessons and queues up to three clean-ups for the PM to answer in its own end-of-day session. Code never rewrites a lesson; the agent does, in its own words.
- Draft fixes. Repeated mistakes become suggested instruction changes you approve with your code. This step arrives in a later release and reads Not built yet until then.
Every step carries one word for its own state: Ran, Missed (it was expected after the last close and left nothing), Not run yet (it runs after the next close), Switched off, or Not built yet for the one still to come, and says when it last ran. When a step is missed the page says so in a sentence above the closed fold, and the day report says so too (the day in words on Overview). Recording is per session, not an after-close step: it reads Missed when sessions were recorded before and none lately, and the sentence then says when the last one was.
Under the steps are the counts behind the page (decisions settled and still open, repeated mistakes tracked, clean-ups queued, lessons you have hidden), how to read a grade (whose grade each small mark stands for; each covers the trailing 60 days, so one day's window overlaps the next: read this month against last month to see change; a grade whose window spans more than one version of a role's set-up says which), and what each role runs under: the version of its context each role currently runs under and why the last one opened (instruction modules changed, an override was enabled or rolled back, the Critic rubric changed, the model policy changed). It links to Portfolio Manager › Settings, the one place those are edited. Memory changing every evening does not open a new version; that is the point of memory.